Arun | Software Developer

ARUN // SOFTWARE ENGINEER

SENIOR SOFTWARE ENGINEER
BACKEND • DATA • AI

Building scalable backend systems,
data platforms, and AI-powered automation.

Software engineer specializing in backend infrastructure, distributed systems, large-scale data processing, and AI applications.

I design high-throughput services, build resilient ETL platforms, and develop intelligent automation systems that scale reliably in production.

PROFILE_DATA

BIOMETRICS / IDENT
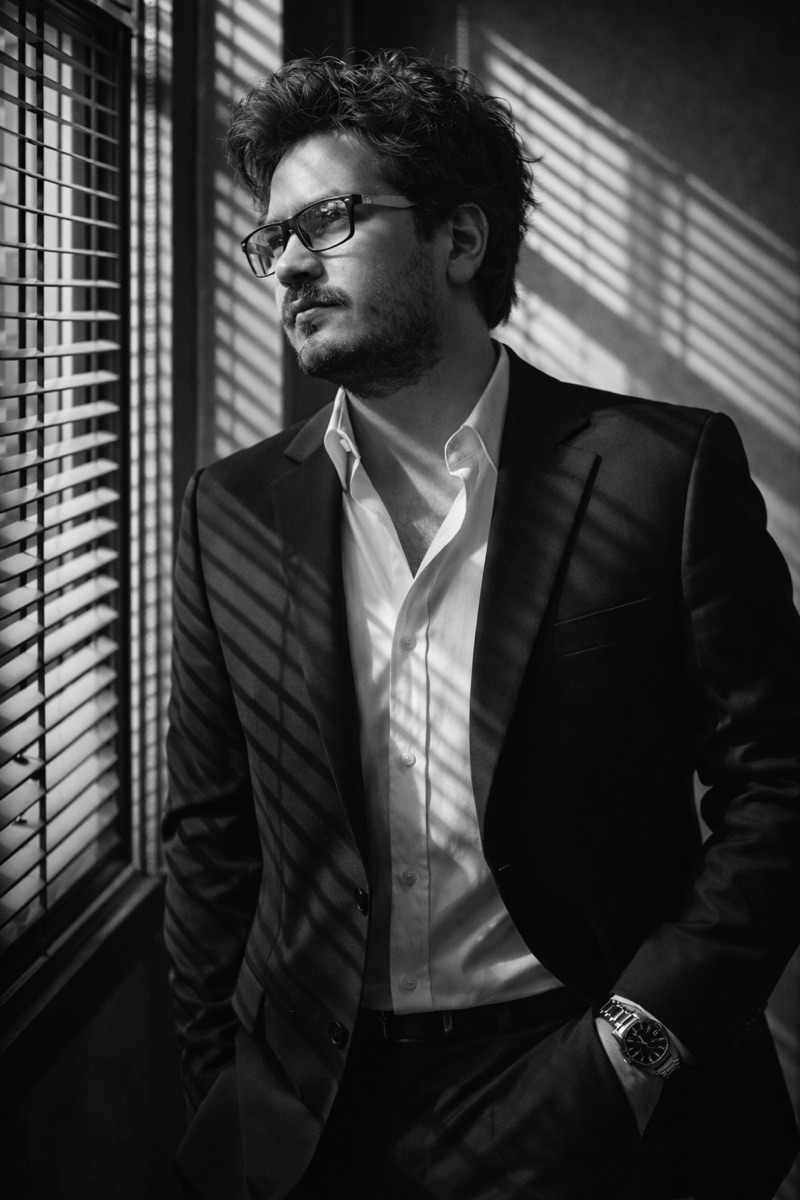
Portrait of Arun Singh

Arun Singh

SENIOR SOFTWARE DEVELOPMENT ENGINEER

B.Tech (Hons.) - Computer Science & Engineering

Indian Institute of Technology Kharagpur

BUILD_STATUS : ACTIVE

CAPABILITIES

WHAT I SHIP
01 // HIGH-THROUGHPUT SERVICES

Stateless backends that hold up under load - multi-service platforms at 3-4k TPS with sub-10ms paths and zero-downtime release trains.

40M+ DATAPOINTS / MONTH

02 // DATA PLATFORMS

Configuration-driven ETL and streaming systems teams can reuse - Airflow fleets, Kafka/Spark pipelines, and ingestion frameworks shared across squads.

30+ ORCHESTRATED WORKFLOWS

03 // APPLIED AI

LLM workflows that cut operational drag - product matching, automation, and research-grade sensing systems shipped beyond the notebook.

75+ HRS SAVED / MONTH

TECH_STACK

RUNTIME / TOOLING
LANGUAGES
Python Node.js TypeScript Rust Java C++
FRAMEWORKS
FastAPI Flask Django
INFRA / DATA
AWS Docker Jenkins Kafka Spark Airflow
ML / COMPUTE
NumPy Pandas TensorFlow PyTorch OpenCV

EXPERIENCE

PROFESSIONAL / RUNTIME
06 / 2023 - PRESENT

Senior Software Development Engineer

ANAKIN (YC S21)
  • Engineered 20+ stateless scraping services processing 40M+ datapoints/month with sub-10ms latency and 3-4k TPS.
  • Developed GPT-powered product matching pipeline processing 5,000+ products/month while saving 75+ operational hours every month.
  • Architected a generic configuration-driven ETL framework used across multiple engineering teams.
  • Designed a scalable multi-account lifecycle system for credential management across 30+ scraping services.
  • Implemented Jenkins-driven CI/CD pipelines enabling zero-downtime deployments.
  • Integrated internal APIs for real-time dashboard driven scraping strategy management.
11 / 2021 - 03 / 2023

Software Development Engineer

AMAZON
  • Developed accounting workflows for EU transportation systems reducing manual effort by 30%.
  • Built modular Apache Airflow data pipelines orchestrating 30+ ETL workflows while reducing processing time by 40%.
  • Integrated mock APIs into CI/CD pipelines increasing load testing coverage by 40%.
  • Migrated AWS CDK infrastructure to satisfy regulatory compliance without downtime.
  • Resolved production bottlenecks and stabilized critical backend pipelines.
10 / 2020 - 11 / 2021

Associate Software Development Engineer

SIGMOID ANALYTICS
  • Designed real-time clickstream analytics using Kafka, Spark and Scala.
  • Built Python automation pipelines reducing manual reporting effort by 80%.
  • Developed scalable data infrastructure for large-scale behavioral analytics.

EDUCATION

FOUNDATION
2016 - 2020

Bachelor of Technology (Hons.)

Computer Science & Engineering

Indian Institute of Technology Kharagpur

AREAS OF EXPERTISE

Domains

  • > Backend Engineering
  • > Cloud Infrastructure
  • > Machine Learning
  • > Distributed Systems

SELECTED_WORK

DEPLOYMENTS
01

GPT Product Matcher

Python LLMs FastAPI

Built an AI-powered product matching engine processing over 5,000 products monthly using large language models to automate product comparison workflows.

02

Generic ETL Framework

Python AWS ETL

Designed a configuration-driven ingestion framework enabling reusable daily data pipelines across multiple engineering teams.

03

Large-scale Scraping Platform

Python Docker AWS

Built a distributed scraping platform composed of 20+ stateless services processing over 40 million datapoints every month with high throughput and low latency.

04

Clickstream Analytics Platform

Kafka Spark Scala

Developed a real-time analytics pipeline for behavioral event processing and large-scale streaming data infrastructure.

05

Synthetic Data Generation

Python Blender PyTorch

Created an automated framework for synthetic dataset generation and trained DETR models for object detection under occluded environments.

RESEARCH

CONFERENCE / PUBLICATIONS

INITIATE_CONTACT

COMMUNICATION / PROTOCOL

Open a
Channel.

Open to roles and collaborations in backend engineering, data infrastructure, and AI systems.

DIRECT_LINE

arunsin997@gmail.com

STATUS

BACKEND_ENGINEER
DATA_INFRASTRUCTURE
AI_SYSTEMS

BUILD_STATUS : ACTIVE